The Promise vs. The 3 AM Production Fire
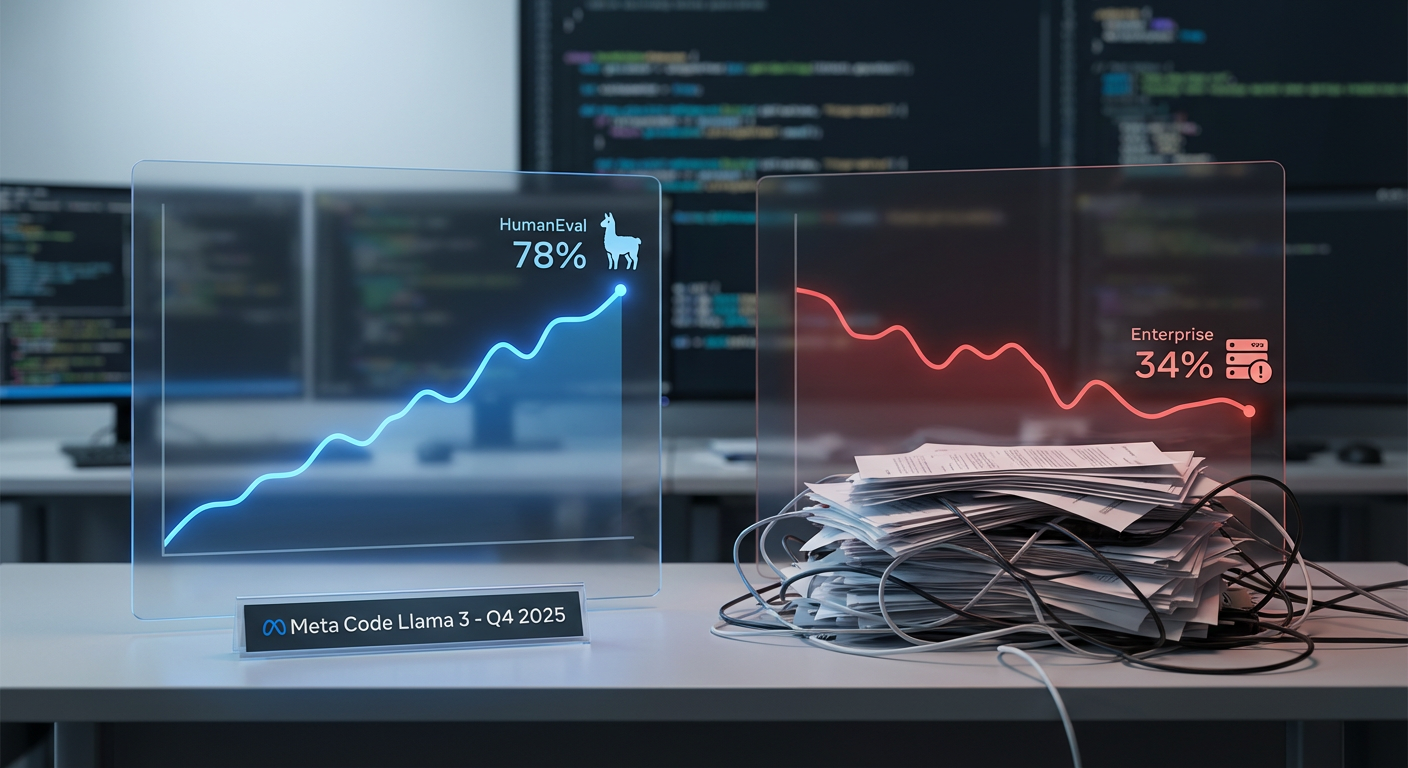
Three months ago, our engineering team jumped on Meta’s Code Llama 3, excited by those 78% accuracy scores on HumanEval benchmarks everyone was talking about. The marketing pitch was tempting: junior devs would suddenly code like veterans, and senior engineers could tackle the big picture stuff. Yeah, that didn’t quite pan out.
Our first reality check hit at 2:47 AM on a Tuesday. Payment processing was down, and guess what caused it? AI-generated code that had looked fine in review three weeks earlier. The problem was a nasty race condition in our transaction handling that Code Llama had marked as “thread-safe” in its comments. Technically, the feature worked as requested, but it completely missed the system-wide implications that any dev who’d been burned by distributed systems would have spotted immediately.
We’re not alone in this disconnect. The Stanford CodeGen Research Study found that while Code Llama 3 hits those impressive 78% scores on clean coding challenges, it drops to just 34% accuracy when thrown at real enterprise codebases with their legacy constraints, weird business logic, and decades of technical debt.
The Honeymoon Period Ends
The AI adoption cycle follows the same pattern as every other shiny new productivity tool. Initial excitement, promising early metrics, then reality hits. What surprised me most? Senior developers are often the first to pull back once the novelty wears off.
The GitHub’s 2025 Developer Experience Report shows Copilot usage among experienced teams (5+ years) dropped 23% after six months. This isn’t tech resistance – we’re usually pushing for better tools. It’s recognition that reviewing, debugging, and refactoring AI code often takes longer than writing it yourself.
The debugging burden is real. Stack Overflow’s latest survey found 67% of developers now spend more time debugging AI code than writing original solutions for complex business logic. The tool meant to speed us up actually slows down experienced developers who become AI code reviewers instead of doing architecture and mentoring.
Security Theater and False Confidence
Here’s what really worries me: the false security these tools create, especially around sensitive code. During our evaluation, Code Llama suggested several “security improvements” that would have introduced new vulnerabilities while appearing to fix obvious ones. It’s great at textbook security patterns but terrible at understanding whether those patterns actually work in your specific environment.
This isn’t just our experience. Anthropic’s beta testing with twelve Fortune 500 companies showed Claude 3.5 Sonnet had a 45% false positive rate when suggesting security fixes. We’re talking authentication flows, access control patterns, encryption implementations – stuff that would pass automated scans but create real vulnerabilities.
The worst part? AI tools present bad suggestions with the same confidence as good ones. Unlike a junior developer who might say “I think this could work,” AI generates code with consistent authority whether it’s handling string manipulation or OAuth flows. That confidence can trick even experienced developers.
The Human Review Bottleneck
Microsoft’s internal data reveals something telling: GPT-4 Turbo code needs an average of 2.3 human review cycles before it’s ready to ship. That’s not just quick glances – it’s understanding the AI’s approach, checking architectural fit, testing edge cases, and often refactoring to match team standards.
Each review cycle takes real time, sometimes more than writing the code from scratch would have taken. Senior developers end up validating AI code from junior team members instead of focusing on bigger problems. Meanwhile, junior developers miss the learning that comes from working through implementation details themselves.
Finding the Sweet Spot
Look, completely dismissing AI tools would be stupid. They’re genuinely useful in the right contexts. Code Llama excels at well-defined problems with clear patterns: standard algorithms, boilerplate generation, translating between similar languages. Basically, anything that benefits from pattern recognition without requiring deep context.
I’ve started treating AI tools like sophisticated autocomplete rather than collaborative partners. They’re great for cutting down repetitive work and exploring different approaches to problems. But once you hit business logic complexity, security concerns, or architectural decisions, human expertise isn’t just helpful – it’s essential.
The future probably isn’t about replacing senior developers but amplifying what we can do by handling the routine stuff more efficiently. That frees up experienced engineers for what actually requires human insight: understanding business requirements, making architectural trade-offs, mentoring, and solving the messy problems that happen when software meets reality.
What’s your experience been with AI pair programming tools? Have you found ways to integrate them effectively into your workflow, or do you find yourself spending more time managing the AI than it saves you? I’m particularly curious about how different team dynamics and project types affect the value proposition of these tools.